Agentic harness validation
Natural language in.
Production-grade stack out.
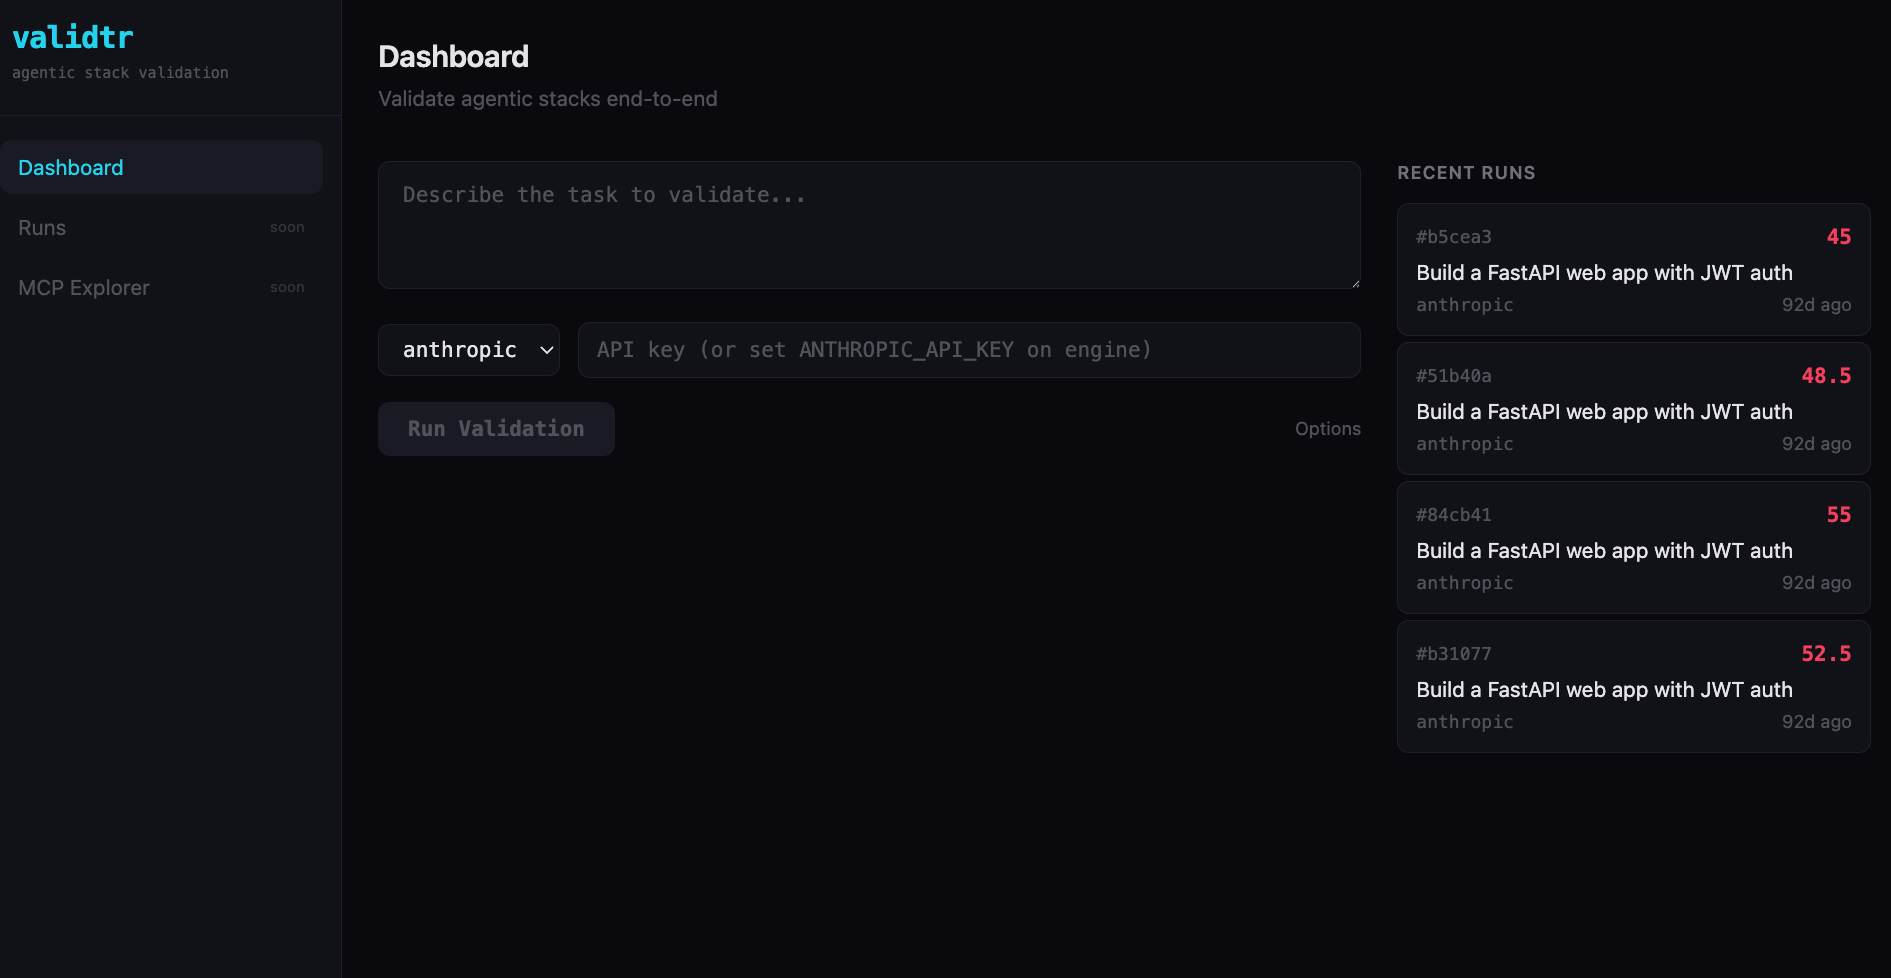
Describe a task in plain English. validtr recommends the optimal agent harness (LLM, framework, MCP servers, skills), provisions it in Docker, executes, generates tests, and scores the result. Below the threshold? It adjusts the stack and retries.
Agent harness validation
Recommends and provisions the full harness (LLM, framework, MCP servers, skills), then executes it in an isolated Docker container.
Token count
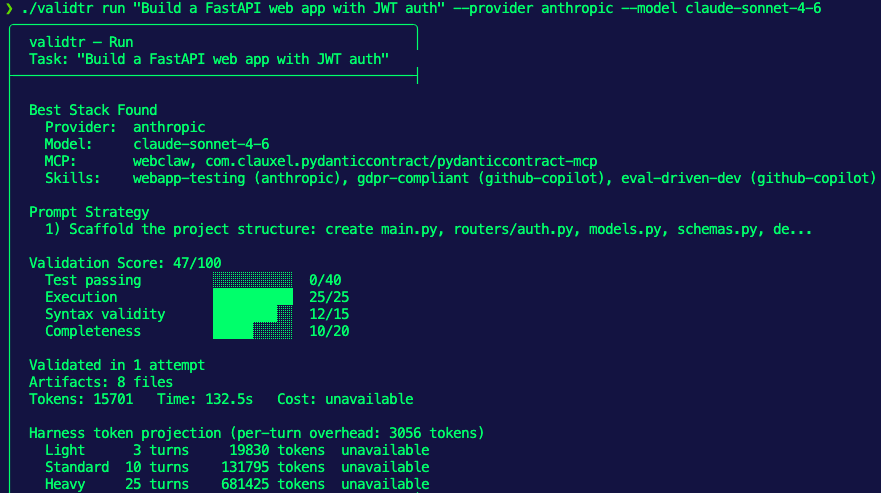
Captures real token usage per run and projects it across Light, Standard, and Heavy workflows, priced from a live catalog.
Scoring
Generates tests from the spec and computes a composite score across test passing, execution, syntax, and completeness, retrying below the threshold.
How it works
One loop, end to end
Every task runs through the same pipeline: analyze the request, recommend and provision a harness, execute it in Docker, generate tests, and score the result, adjusting the stack and retrying until it clears your threshold.
task
harness
See it in action
From prompt to validated harness
Scored, end to end
Every run, scored and projected
Start here
New user path
Understand validtr
The high-level architecture and workflow before your first run.
Fastest path
Run a task in minutes
Start the engine, run a task, inspect the scored output with retries.
CLI guide
Browse all commands
Docs for run, mcp, config, completion, help.
Engine API
Inspect contracts
Endpoints, payload fields, examples, and error behavior.